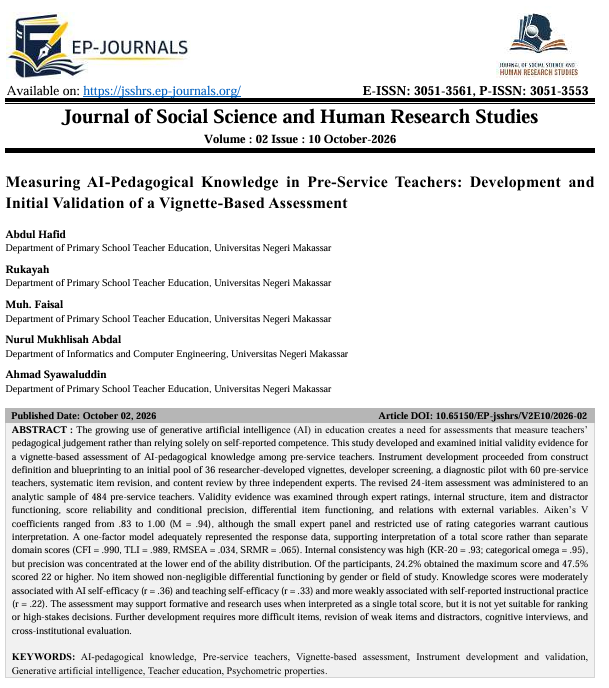
Measuring AI-Pedagogical Knowledge in Pre-Service Teachers: Development and Initial Validation of a Vignette-Based Assessment
DOI:
https://doi.org/10.65150/EP-jsshrs/V2E10/2026-02Keywords:
AI-pedagogical knowledge, Pre-service teachers, Vignette-based assessment, Instrument development and validation, Generative artificial intelligence, Teacher education, Psychometric properties.Abstract
The growing use of generative artificial intelligence (AI) in education creates a need for assessments that measure teachers’ pedagogical judgement rather than relying solely on self-reported competence. This study developed and examined initial validity evidence for a vignette-based assessment of AI-pedagogical knowledge among pre-service teachers. Instrument development proceeded from construct definition and blueprinting to an initial pool of 36 researcher-developed vignettes, developer screening, a diagnostic pilot with 60 pre-service teachers, systematic item revision, and content review by three independent experts. The revised 24-item assessment was administered to an analytic sample of 484 pre-service teachers. Validity evidence was examined through expert ratings, internal structure, item and distractor functioning, score reliability and conditional precision, differential item functioning, and relations with external variables. Aiken’s V coefficients ranged from .83 to 1.00 (M = .94), although the small expert panel and restricted use of rating categories warrant cautious interpretation. A one-factor model adequately represented the response data, supporting interpretation of a total score rather than separate domain scores (CFI = .990, TLI = .989, RMSEA = .034, SRMR = .065). Internal consistency was high (KR-20 = .93; categorical omega = .95), but precision was concentrated at the lower end of the ability distribution. Of the participants, 24.2% obtained the maximum score and 47.5% scored 22 or higher. No item showed non-negligible differential functioning by gender or field of study. Knowledge scores were moderately associated with AI self-efficacy (r = .36) and teaching self-efficacy (r = .33) and more weakly associated with self-reported instructional practice (r = .22). The assessment may support formative and research uses when interpreted as a single total score, but it is not yet suitable for ranking or high-stakes decisions. Further development requires more difficult items, revision of weak items and distractors, cognitive interviews, and cross-institutional evaluation.
References
1) Aiken, L. R. (1985). Three Coefficients for Analyzing the Reliability and Validity of Ratings. Educational and Psychological Measurement, 45(1), 131–142. https://doi.org/10.1177/0013164485451012
2) American Educational Research Association, A. E. R. A., American Psychological Association, A. P. A., & National Council on Measurement in Education, N. C. on M. in E. (2014). Standards for educational and psychological testing. American Educational Research Association.
3) Andersen, E. B. (1973). A Goodness of Fit Test for the Rasch Model. Psychometrika, 38(1), 123–140. https://doi.org/10.1007/BF02291180
4) Bandura, A. (2006). Guide to the construction of self-efficacy scales. In F. Pajares & T. Urdan (Ed.), Self-efficacy beliefs of adolescents (Vol. 5). Information Age Publishing.
5) Chiu, T. K. F., Ahmad, Z., & Çoban, M. (2025). Development and validation of teacher artificial intelligence (AI) competence self-efficacy (TAICS) scale. Education and Information Technologies, 30(5), 6667–6685. https://doi.org/10.1007/s10639-024-13094-z
6) Choudhury, S., Deb, J. P., Pradhan, P., & Mishra, A. (2024). Validation of the Teachers AI-TPACK Scale for the Indian Educational Setting. International Journal of Experimental Research and Review, 43, 119–133. https://doi.org/10.52756/ijerr.2024.v43spl.009
7) Depaepe, F., & König, J. (2018). General pedagogical knowledge, self-efficacy and instructional practice: Disentangling their relationship in pre-service teacher education. Teaching and Teacher Education, 69, 177–190. https://doi.org/10.1016/j.tate.2017.10.003
8) Doss, C. J., Bozick, R., Schwartz, H. L., Chu, L., Rainey, L. R., Woo, A., Reich, J., & Dukes, J. (2025). AI Use in Schools Is Quickly Increasing but Guidance Lags Behind: Findings from the RAND Survey Panels. RAND Corporation. https://doi.org/10.7249/RRA4180-1
9) Haladyna, T. M., & Rodriguez, M. C. (2013). Developing and validating test items. In Developing and Validating Test Items. https://doi.org/10.4324/9780203850381
10) Jin, Y., Martinez-Maldonado, R., Gašević, D., & Yan, L. (2025). GLAT: The generative AI literacy assessment test. Computers and Education: Artificial Intelligence, 9, 100436. https://doi.org/10.1016/j.caeai.2025.100436
11) Jodoin, M. G., & Gierl, M. J. (2001). Evaluating Type I Error and Power Rates Using an Effect Size Measure With the Logistic Regression Procedure for DIF Detection. Applied Measurement in Education, 14(4), 329–349. https://doi.org/10.1207/S15324818AME1404_2
12) Kerr, R. C., & Kim, H. (2025). From Prompts to Plans: A Case Study of Pre-Service EFL Teachers’ Use of Generative AI for Lesson Planning. English Teaching, 80(1), 95–118. https://doi.org/10.15858/engtea.80.1.202503.95
13) Liang, W., Yuksekgonul, M., Mao, Y., Wu, E., & Zou, J. (2023). GPT detectors are biased against non-native English writers. Patterns, 4(7), 100779. https://doi.org/10.1016/j.patter.2023.100779
14) Lievens, F., & Motowidlo, S. J. (2016). Situational Judgment Tests: From Measures of Situational Judgment to Measures of General Domain Knowledge. Industrial and Organizational Psychology, 9(1), 3–22. https://doi.org/10.1017/iop.2015.71
15) Mair, P., & Hatzinger, R. (2007). Extended Rasch Modeling: The eRm Package for the Application of IRT Models in R. Journal of Statistical Software, 20(9). https://doi.org/10.18637/jss.v020.i09
16) Markus, A., Carolus, A., & Wienrich, C. (2025). Objective measurement of AI literacy: Development and validation of the AI competency objective scale (AICOS). Computers and Education: Artificial Intelligence, 9, 100485. https://doi.org/10.1016/j.caeai.2025.100485
17) Miao, F., & Cukurova, M. (2024). AI competency framework for teachers. UNESCO. https://doi.org/10.54675/ZJTE2084
18) Ning, Y., Zhang, C., Xu, B., Zhou, Y., & Wijaya, T. T. (2024). Teachers’ AI-TPACK: Exploring the Relationship between Knowledge Elements. Sustainability, 16(3), 978. https://doi.org/10.3390/su16030978
19) Penfield, R. D., & Giacobbi, Jr., P. R. (2004). Applying a Score Confidence Interval to Aiken’s Item Content-Relevance Index. Measurement in Physical Education and Exercise Science, 8(4), 213–225. https://doi.org/10.1207/s15327841mpee0804_3
20) Podsakoff, P. M., MacKenzie, S. B., Lee, J.-Y., & Podsakoff, N. P. (2003). Common method biases in behavioral research: A critical review of the literature and recommended remedies. Journal of Applied Psychology, 88(5), 879–903. https://doi.org/10.1037/0021-9010.88.5.879
21) Praetorius, A.-K., Klieme, E., Herbert, B., & Pinger, P. (2018). Generic dimensions of teaching quality: the German framework of Three Basic Dimensions. ZDM – Mathematics Education, 50(3), 407–426. https://doi.org/10.1007/s11858-018-0918-4
22) Setiyawan, A., Soeharto, S., Wijaya, T. T., Korenova, L., & Lavicza, Z. (2025). Measuring Teachers’ competencies for AI integration: Development and validation of the AI-TPACK in vocational education. Computers and Education Open, 9, 100319. https://doi.org/10.1016/j.caeo.2025.100319
23) Steiger, J. H. (1980). Tests for comparing elements of a correlation matrix. Psychological Bulletin, 87(2), 245–251.
https://doi.org/10.1037/0033-2909.87.2.245
24) Swaminathan, H., & Rogers, H. J. (1990). Detecting Differential Item Functioning Using Logistic Regression Procedures. Journal of Educational Measurement, 27(4), 361–370. https://doi.org/10.1111/j.1745-3984.1990.tb00754.x
25) Tschannen-Moran, M., & Hoy, A. W. (2001). Teacher efficacy: capturing an elusive construct. Teaching and Teacher Education, 17(7), 783–805. https://doi.org/10.1016/S0742-051X(01)00036-1
26) Zhang, S., Xiao, R., Botelho, A. F., Liao, G., Chiu, T. K. F., Stamper, J., & Koedinger, K. R. (2026). How to Assess AI Literacy: Misalignment Between Self-Reported and Objective-Based Measures. Proceedings of the LAK26: 16th International Learning Analytics and Knowledge Conference, 405–414. https://doi.org/10.1145/3785022.3785088
Downloads
Published
Issue
Section
License
Copyright (c) 2026 Abdul Hafid, Rukayah, Muh. Faisal, Nurul Mukhlisah Abdal, Ahmad Syawaluddin (Author)

This work is licensed under a Creative Commons Attribution 4.0 International License.