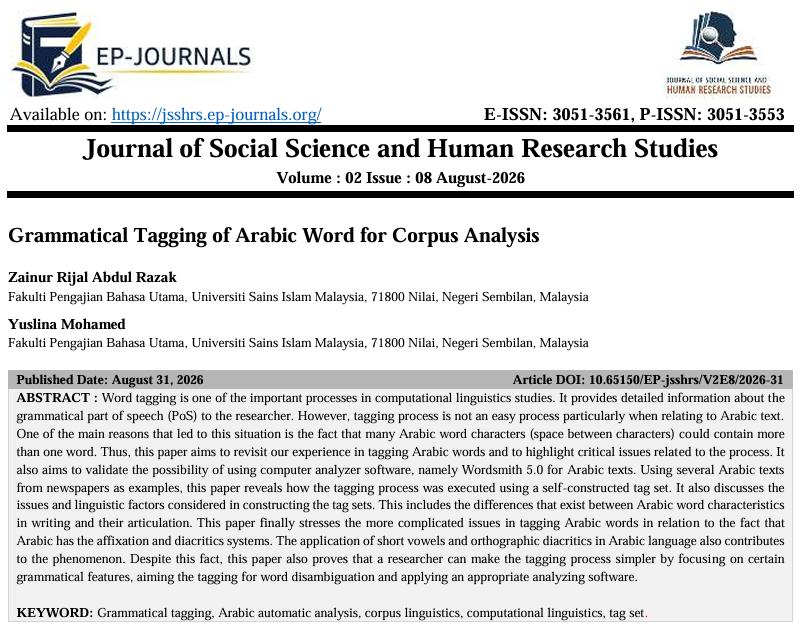
Grammatical Tagging of Arabic Word for Corpus Analysis
DOI:
https://doi.org/10.65150/EP-jsshrs/V2E8/2026-31Keywords:
Grammatical tagging, Arabic automatic analysis, corpus linguistics, computational linguistics, tag set.Abstract
Word tagging is one of the important processes in computational linguistics studies. It provides detailed information about the grammatical part of speech (PoS) to the researcher. However, tagging process is not an easy process particularly when relating to Arabic text. One of the main reasons that led to this situation is the fact that many Arabic word characters (space between characters) could contain more than one word. Thus, this paper aims to revisit our experience in tagging Arabic words and to highlight critical issues related to the process. It also aims to validate the possibility of using computer analyzer software, namely Wordsmith 5.0 for Arabic texts. Using several Arabic texts from newspapers as examples, this paper reveals how the tagging process was executed using a self-constructed tag set. It also discusses the issues and linguistic factors considered in constructing the tag sets. This includes the differences that exist between Arabic word characteristics in writing and their articulation. This paper finally stresses the more complicated issues in tagging Arabic words in relation to the fact that Arabic has the affixation and diacritics systems. The application of short vowels and orthographic diacritics in Arabic language also contributes to the phenomenon. Despite this fact, this paper also proves that a researcher can make the tagging process simpler by focusing on certain grammatical features, aiming the tagging for word disambiguation and applying an appropriate analyzing software.
References
1) Abdelkader, D.O., Mohamed Yagi, S. & Sawalha, M.S. (2024). Source of syntactic ambiguity of contemporary Arabic: A corpus study. Jordanian Education Journal, 9(3), 27-46. https://doi.org/10.46515/jaes.v9i3.869
2) Abdul Razak, Z.R. (2011). Modern Media Arabic: Study of Word Frequency in World Affairs and Sports Sections in Arabic Newspapers. Unpublished Phd Thesis. Birmingham: University of Birmingham.
3) Abdurashetovna, Manzura, A. (2023). Tagging and annotation of corpus units. International Journal of Language Learning and Applied Linguistics, 2(12), 103-107.
4) Al-Shamsi, F. and Guessoum, A. (2006). A Hidden Markov Model-Based POS Tagger for Arabic. 8es Journees Internationales d’Analyse Statistique des Donnees Textuelles, 31-42.
5) Al-Thaani, A. and Abu al-Rub, S. (2009). A Rule-Based Approach for Tagging Non-Vocalized Arabic Words. The International Arab Journal of Information Technology 6 (3), 320-328.
6) Awwalu, J., Abdullahi, S.Y & Evwickpaefe, A.E. (2020). Part of speech tagging: A review of techniques. FUDMA Journal of Science, 4(2), 712-721. https://doi.org/10.33003/fjs-2020-0402-325
7) Baker, P, A Hardie and T McEnery. (2006). A Glossary of Corpus Linguistics. Edinnburgh: Edinburgh University Press.
8) Boudchiche, M. & Mazroui, A. (2015). Evaluation of the ambiguity caused by the absence of diacritical marks in Arabic texts: Statistical study. Proceeding of the 2015 5th International Conference on Information & Communication Technology and Accessibility (ICTA), Marrakech, Morocco. https://doi.org/10.1109/ICTA.2015.7426904
9) Branco, A. and Silva, J. (n.d.). EtiFAC: A Facilitating Tool for Manual Tagging. Accessed on February 28, 2012, from http://www.di.fc.ul.pt/~ahb/BrancoSilva.
10) Crystal, D. (2003). A Dictionary of Linguistics and Phonetics, 5th ed. Oxford: Blackwell.
11) Diab, M., K. Hacioglu and D. Jurafsky. (2004). Automatic Tagging of Arabic Text: From Raw Text to Base Phrase Chunks. Proceedings of HLT-NAACL 2004, East Stroudsburg, Pennsylvania.
12) Dwivedi, V. (2024). Natural language processing. In Data Science for Beginners. EDSOL Informatics.
13) Habash, N. (2010). Introduction to Arabic Natural Language Processing. Morgan & Claypool Publishers.
14) Habash, N. and O. Rambow. (2005). Arabic Tokenization, Part-of-Speech Tagging and Morphological Disambiguition in One Fell Swoop. Proceeding of the 43rd Annual Meeting of the ACL 2005, Michigan: Association for Computational Linguistics.
15) Isam, H. and Mat Awal, N. (2011). Analisis Berasaskan Korpus Dalam Menstruktur Semula Kedudukan Makna Teras Leksikal Setia. GEMA Onlinetm Journal of Language Studies, 11, (1), 143-158.
16) Kubler, S. and Mohamed, E. (2011). Part of Speech Tagging for Arabic. Cambridge Journal Online. Accessed on February 28, 2012, from http://journals.cambridge.org/action.
17) McEnery, T. and A. Wilson. (1996). Corpus Linguistics. Edinburgh: Edinburgh University Press.
18) Minerva, S. (2025). Enhancing glass-box methods for part-of-speech tagging and text classification. [Doctoral dissertation, , Chalmers University of Technology].
Chrome-extension://efaidnbmnnnibpcajpcglclefindmkaj/https://research.chalmers.se/publication/546192/file/546192_Fu
19) Scott, M. (n.d) Wordsmith tools. https://lexically.net/wordsmith/research/ (Accessed on August 24, 2026.
20) Van Mol, M. (2003). Variation in Modern Standard Arabic in Radio News Broadcasts: A Synchronic Descriptive Investigation into the Use of Complementary Particles. Paris: Peeters and Department of Oriental Studies.
21) Yamina, T.G. (2005). Tagging by Combining Rules-Based Method and Memory-Based Learning. Journal of World Academy of Science, Engineering and Technology 6, 110-114.
Downloads
Published
Issue
Section
License
Copyright (c) 2026 Zainur Rijal Abdul Razak, Yuslina Mohamed (Author)

This work is licensed under a Creative Commons Attribution 4.0 International License.